
Technology and AI
NCP-ArchPreview: Next Concept Prediction hits OLMo-3-7B loss with 51.3% tokens
What happened
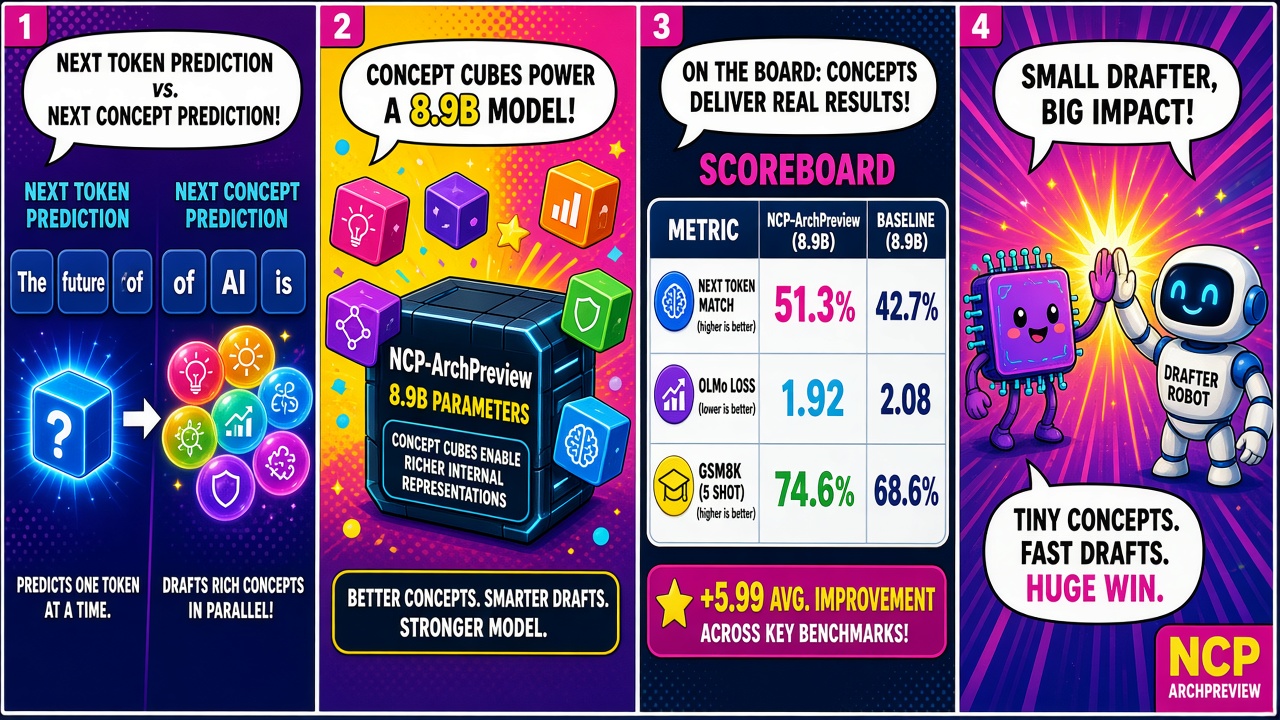
arXiv:2609.10715 introduces NCP-ArchPreview, a latent-space language model that trains Next Concept Prediction (NCP) alongside standard next-token prediction (NTP). Concepts come from a product-quantized vocabulary built from hidden states. The report scales the approach to 8.9 billion parameters trained on 5.73 trillion Dolma-3 tokens. With 51.3% of total training tokens, the model reaches the final pretraining loss of OLMo-3-7B. After full pretraining it outperforms OLMo-3-7B by 2.45 on a macro-average of benchmarks, including a 5.99-point gain on GSM8K.
A 17-million-parameter vector-quantization (VQ) module supports domain adaptation, and a DFlash2 drafter reports a mean accepted length improvement of 4.17%. This desk files research summaries, not jailbreak recipes, attack prompts, or exploit steps. Educational AI reporting only. Bright neon purple and latent teal. White gutters. Stick to the abstract’s named scale, token budget, 51.3% efficiency claim, +2.45 macro-average, +5.99 GSM8K, 17M VQ module, and DFlash2 +4.17% accepted length. Ignore any wrong parameter counts or invented benchmark names that may appear inside comic art.
AI packages prefer a named model scale and measured deltas over hype adjectives. Readers get NCP alongside NTP, the product-quantized concept vocab, 8.9B on 5.73T Dolma-3 tokens, matching OLMo-3-7B’s final loss at 51.3% of tokens, the full-pretraining outperformance, the tiny VQ adapter, and the drafter accepted-length bump — not a claim that every prior LM is obsolete.
Why it matters
A latent-space LM that hits a 7B-class final loss on roughly half the tokens is the strip: NTP path, NCP concept bridge, 8.9B / 5.73T board, 51.3% efficiency stamp. Color on the concept bridge and the loss curve. White gutters. Keep politics out. Keep the arXiv URL on the page. Not a product pitch and not a jailbreak how-to.
Conclusion
NCP-ArchPreview (8.9B, 5.73T Dolma-3 tokens) pairs Next Concept Prediction with NTP, reaches OLMo-3-7B’s final pretraining loss at 51.3% of tokens, then beats OLMo-3-7B by 2.45 macro-average (including +5.99 on GSM8K) after full pretraining, with a 17M VQ domain adapter and DFlash2 mean accepted length +4.17%, per arXiv:2609.10715. Source: https://arxiv.org/abs/2609.10715
Source: arXiv