
Technology and AI
EMNLP 2026: Attention sinks tied to self-concentration, not RoPE
What happened
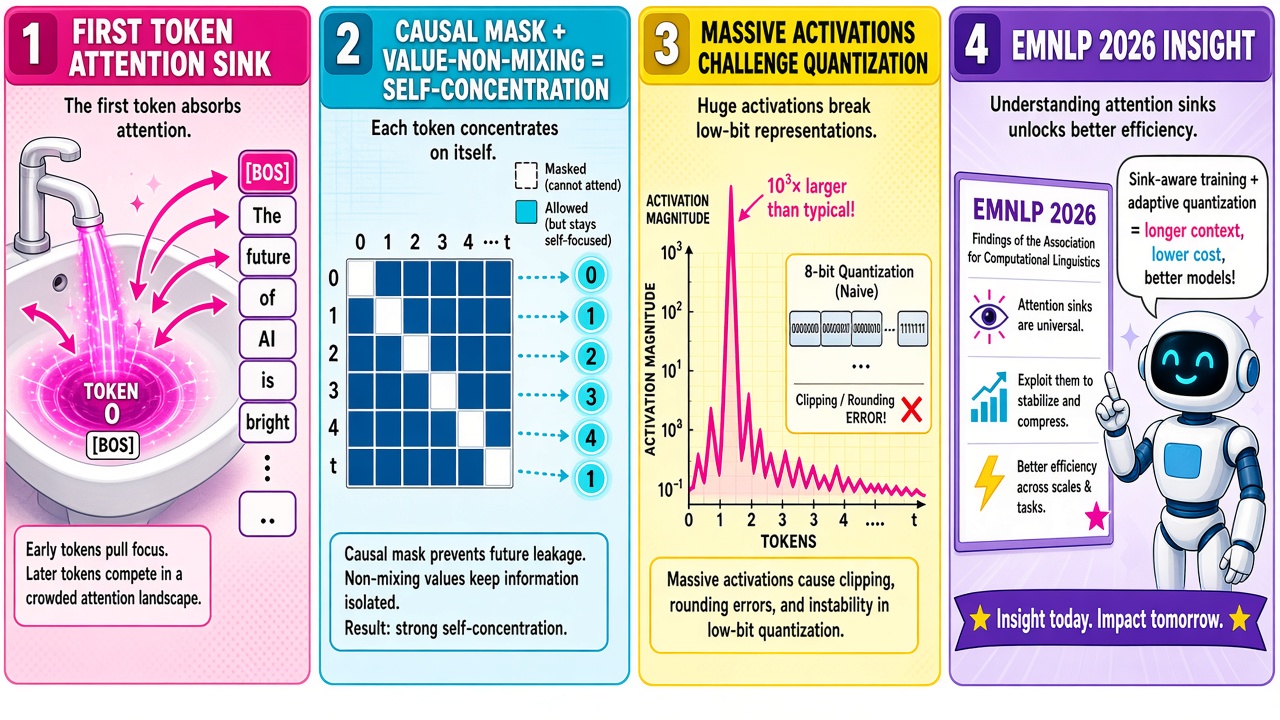
arXiv:2609.09085, accepted at EMNLP 2026, analyzes why Large Language Models often exhibit “Attention Sink” (AS) and accompanying “Massive Activations” (MAs) at the initial position of a sequence — phenomena that frequently co-occur, with MAs posing challenges for low-bit quantization. The paper’s title frames the claim directly: it is not RoPE that creates sinks. Experiments suggest self-concentration of attention, resulting from the causal mask, and subsequent Value-non-mixing in attention outputs contribute to AS and MAs at the initial position regardless of which token occupies it.
Authors include Raito Kiya and colleagues; the abstract stays at mechanism-level evidence and quantization insight rather than product benchmarks. This desk files research summaries, not jailbreak recipes, attack prompts, or exploit steps. Educational AI reporting only. Bright neon purple and latent teal. White gutters. Stick to the abstract’s named phenomena — Attention Sink, Massive Activations, initial-position focus, causal-mask self-concentration, Value-non-mixing, and quantization implications. Do not invent extra percentages, parameter counts, or “universal sink” slogans that may appear inside comic art; if a panel overclaims beyond the abstract, the verified prose wins.
AI packages prefer a named venue and a clear mechanism claim over hype adjectives. Readers get EMNLP 2026 acceptance, arXiv:2609.09085, AS and MAs at the first position, the causal-mask self-concentration path, Value-non-mixing in attention outputs, and the quantization angle — not a claim that every prior positional-encoding story is obsolete.
Why it matters
A paper that relocates attention-sink causes from RoPE to self-concentration plus Value-non-mixing is the strip: first-token sink, causal-mask board, massive-activation spike, EMNLP 2026 stamp. Color on the sink drain and the activation spike. White gutters. Keep politics out. Keep the arXiv URL on the page. Not a product pitch and not a jailbreak how-to.
Conclusion
EMNLP 2026 paper arXiv:2609.09085 argues Attention Sink and Massive Activations at the initial sequence position arise from causal-mask self-concentration and Value-non-mixing in attention outputs — not from RoPE — with implications for understanding attention dynamics and informing quantization strategies. Source: https://arxiv.org/abs/2609.09085
Source: arXiv